Model structure
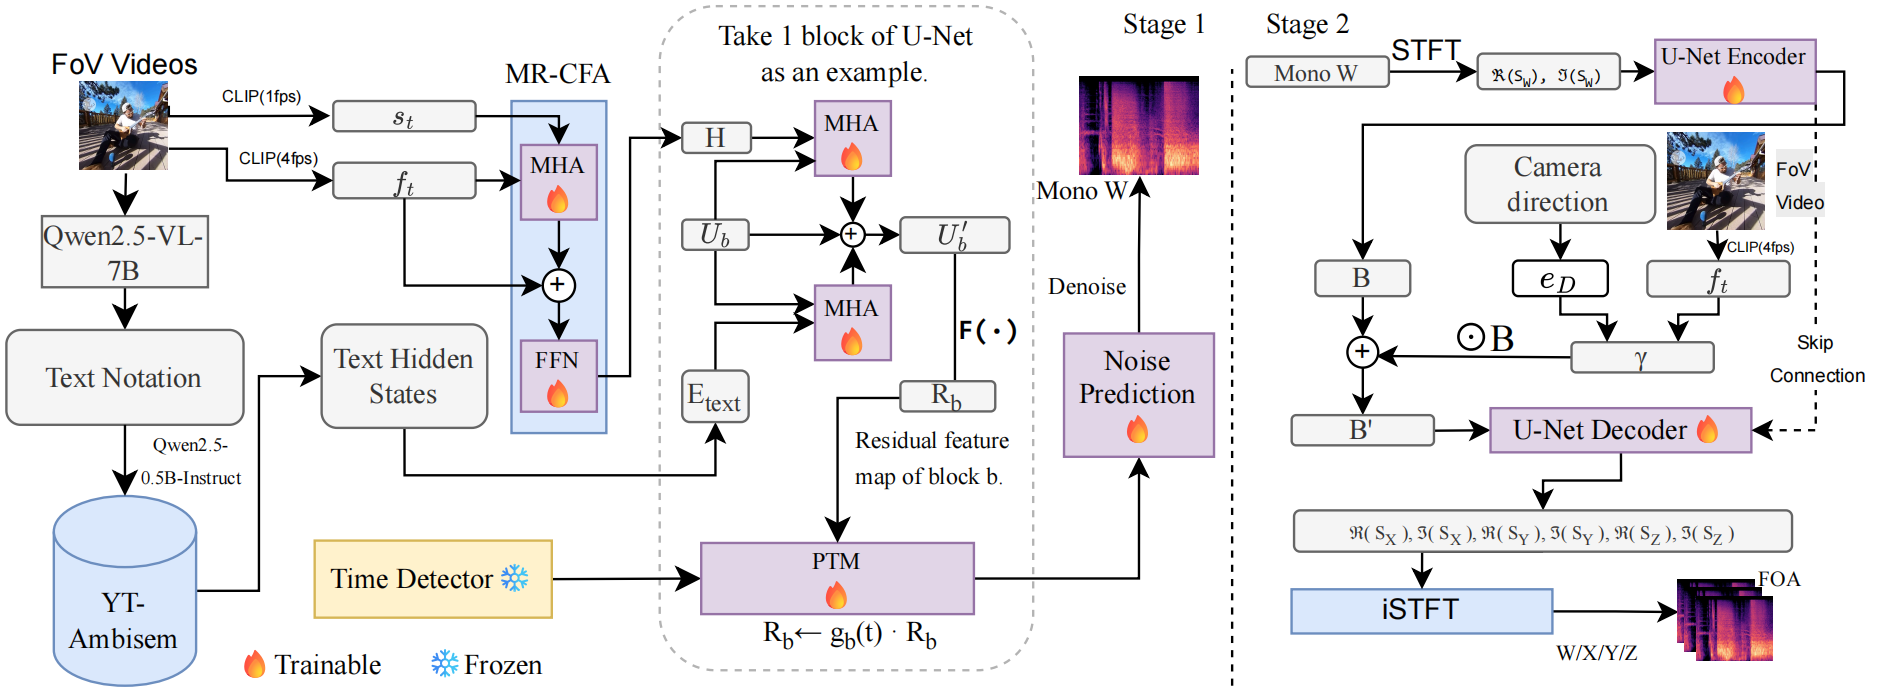
We study immersive video-to-audio (V2A) by generating first-order ambisonics (FOA) from silent field-of-view videos. Existing immersive V2A systems struggle with (i) sparse semantics in public video–FOA corpora, and (ii) content–geom\-etry entanglement: end-to-end models blur “what” and “where”, while naive two-stage pipelines trade semantic fidelity for spatial coherence. We present FoleyImmersive, a decoupled, two-stage framework and a semantics-augmented dataset YT-AmbiSem, which enriches all YT-Ambigen clips with structured descriptions using Qwen2.5-VL. FoleyImmersive decouples what and where into two stages: Stage 1 uses a semantics-first diffusion model with multi-rate cross-frame attention and a probabilistic time modulator to produce a well-semantic mono W. Stage 2 spatializes W to XYZ with a complex-STFT U-Net conditioned on per-frame visuals and camera direction, where a lightweight directional residual mixer applies view-dependent gating at the bottleneck to stabilize localization with minimal content drift. Our method achieves state-of-the-art semantic and spatial metrics.
We provide a download link for the YT-AMBISEM dataset.